Key facts
| Developer | Google DeepMind |
|---|---|
| Release date | Announced — May 2026 (Google I/O); Omni 1.1 Flash — August 27, 2026 |
| What it does | Creates and edits video with sound from text, images and video |
| Duration | 3–10 seconds per generation, extension by 10 seconds up to 40 seconds |
| Resolution | 360p, 720p; 1080p and 4K by upscale; 24 frames per second |
| Frame formats | 16:9 and 9:16 |
| References | Images and up to 3 videos of 3 seconds each |
| Sound | Generated together with the video |
| Labeling | Invisible SynthID watermark |
| In AI2Face | Yes, Omni 1.1 Flash in the generator |
What Gemini Omni is
Gemini Omni is a family of Google DeepMind models that create content from any input. Video came first. Google showed the model at I/O in May 2026 and described it this way: “imagine Nano Banana, but for video” — you can refine the result at any step with ordinary phrases.
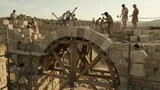
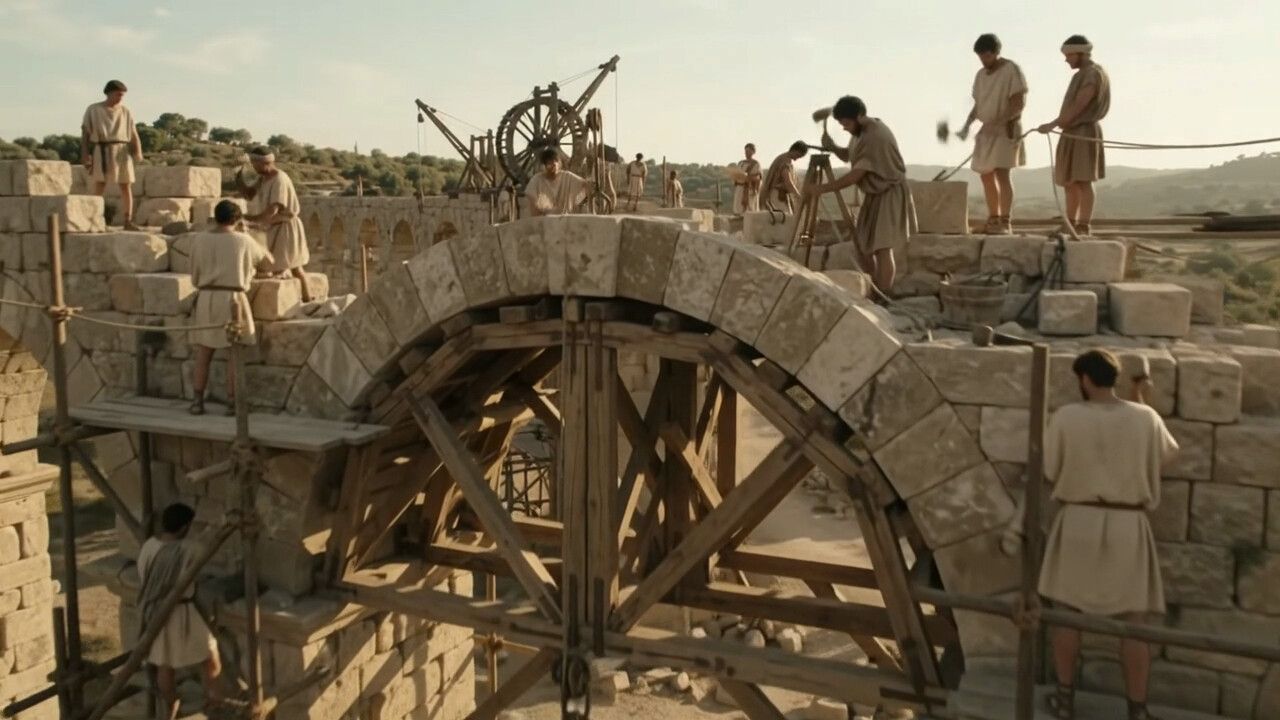
Omni draws on Gemini’s knowledge of the world: physics, history, science and culture. So a scene like “building an aqueduct in the 1st century” or “how a canal lock works” comes out with plausible detail, not only a pretty picture.
On August 27, 2026, Omni 1.1 Flash came out — a stable version with scene extension, control of the first and last frame, 360p drafts and output up to 4K. In the Gemini API documentation, Google recommends it as the default video model, and Veo 3.1 for specific tasks.
What Gemini Omni can do
World knowledge. The model fills in historically and physically plausible detail when you ask for a scene from a real context.
A scene from several references. The woman from one photo, the dress from another, the loft from a third — Omni assembles them into one clip and keeps the look.
Editing a finished clip. The main difference from Veo: upload a video and describe the change — weather, clothes, light, objects, camera movement. Each next edit builds on the previous one.
First and last frame. Two pictures, and the model builds the transition between them with sound.
Photo to video. The image becomes the first frame of the clip: smoke, drops, camera movement.
Extension. In the API a clip extends in steps of 10 seconds up to 40 seconds, and the model takes up to 10 seconds of the previous video into account, not only the last frame.
What Gemini Omni is good for
- Editing finished clips: change the weather, the time of day or the clothes, or remove an object, without a reshoot.
- Educational and historical scenes, where plausible detail matters.
- Ads from a product photo: a product shot becomes a short clip.
- Short vertical clips for social networks, with sound.
- Fast iterations: a draft at 360p, a final at 1080p or 4K.
Gemini Omni and alternatives
| Gemini Omni 1.1 Flash | Veo 3.1 | Seedance 2.5 | |
|---|---|---|---|
| Developer | Google DeepMind | Google DeepMind | ByteDance Seed |
| Length per generation | 3–10 s | 4, 6, 8 s | up to 30 s |
| Extension | up to 40 s | up to 148 s (API, 720p) | 2 times |
| Resolution | up to 4K (upscale) | up to 4K | not disclosed |
| Inputs | text, images, video | text, up to 3 images | text, 30 photos, 10 videos, 10 audio |
| Editing a finished video | yes, with phrases | no | yes |
| Speech languages | fully — English | not published | not published |
| In AI2Face | yes | yes | yes |
Omni is the most flexible of Google’s models: it edits video and accepts video as input. Veo 3.1 wins on the quality of an 8-second clip and a precise last-frame mode. Seedance 2.5 makes the longest clips in one generation.
How to write prompts for Gemini Omni
- For generation — the same formula as for Veo: camera + subject + action + setting + style, and the sound separately.
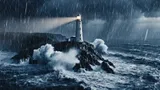
- For an edit — one change at a time, and say what to keep: “Change the weather to a sunny day. Keep the camera movement, the composition and the lighthouse.”
- For references — say what to take from each picture: “the woman from the first image in the dress from the second, in the loft from the third.”
- For iterations — start at 360p: Google says a draft generates up to 60% faster and costs three times less than 720p.
- Write lines in English when you can: Google has not officially evaluated the other languages.
Change the weather in this video to a calm, sunny summer day: a clear blue sky,
a calm turquoise sea with small waves, bright sun on the white lighthouse and green grass
on the cliff. Keep the same camera movement, composition and lighthouse. Sound: calm waves and seagulls
instead of the storm
How to use Gemini Omni in AI2Face
- Open the generator, choose video and the model Gemini Omni 1.1 Flash.
- Choose a mode: from text, from a photo, from references (up to 6 images) or from a first and last frame.
- Set the duration (4, 6, 8 or 10 seconds), the format (16:9 or 9:16) and the resolution.
- Start the generation — the cost is shown beforehand.
Editing a finished video and extension are in the AI2Face generator. An image from Nano Banana 2 or Seedream can go straight in as the first frame of the clip. Omni is available in the AI2Face generator, and the cost is shown before you generate.
Limitations
- Languages. English is fully supported; Google has not evaluated the other languages.
- Sound. You can’t edit the voice, and audio references are not supported in the API yet.
- Extending speech. You can’t extend an uploaded video in which a person is speaking in order to add new lines.
- Complex motion and text. On the model card, Google names full consistency across edits, complex dynamics and accurate text in the frame as difficulties.
- Regions. Storing and editing video are unavailable in the EEA, Switzerland and the United Kingdom.
- Labeling. Every clip contains SynthID; you can check the mark in the Gemini app, Chrome and Google Search.
Conclusions
Gemini Omni is Google’s everyday video model: flexible on inputs, with sound, and — the main point — with editing of a finished clip by ordinary phrases. Use it for clips from photos and references, educational scenes and fast iterations. For the highest quality of an 8-second clip and a precise move to the last frame, choose Veo 3.1. For long stories in one generation, choose Seedance 2.5. In AI2Face, Omni is available alongside the image models: a frame from the generator becomes the first frame of the video.
FAQ
What is Gemini Omni?
A Google DeepMind video model that creates a clip from any mix of text, images and video and edits it with ordinary phrases. The first version of the family is Gemini Omni Flash; the current one is Omni 1.1 Flash.
How is Gemini Omni different from Veo 3.1?
Omni takes more kinds of input and can edit a finished clip in a dialogue, while Veo 3.1 gives the highest quality of a short clip. Google recommends Omni as the default video model, and Veo for extending scenes, the last-frame mode and older pipelines.
How many seconds of video does Gemini Omni make?
From 3 to 10 seconds in one generation. You can extend a clip by 10 seconds up to 40 seconds. In AI2Face, 4, 6, 8 and 10 seconds are available.
Does it understand languages other than English?
Google fully documents English only; other languages aren't officially evaluated. Dialogue is more reliable in English. Prompts in other languages, including the Russian ones in our tests, are usually understood.
Where is the official Gemini Omni website?
There is no separate site. Officially Gemini Omni runs in the Gemini app, in YouTube Shorts and YouTube Create, in Google AI Studio and through the Gemini API. Domains with “omni” in the name belong to third-party services.
Can you try Gemini Omni for free?
At Google — free in YouTube Shorts and YouTube Create; in the Gemini app, with a Google AI Plus, Pro or Ultra subscription. In AI2Face, Omni is available in the generator on credits, and the cost is shown before you generate. Welcome credits are added after you sign up.
Sources
6
- https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-omni/
- https://blog.google/innovation-and-ai/technology/developers-tools/build-with-gemini-omni-1-1-flash/
- https://ai.google.dev/gemini-api/docs/omni
- https://deepmind.google/models/model-cards/gemini-omni-flash/
- https://ai.google.dev/gemini-api/docs/veo
- https://seed.bytedance.com/en/blog/one-take-creation-flexible-referencing-introducing-seedance-2-5